Coding agent 的 focus 能否弥补 Text-world model 和 Vision-world model 的 gap
- Text-world model 和 Vision-world model 是否有 gap?
- 让 coding agent 先用代码把 focus 建出来,能不能弥补这个 gap?
- focus 在哪里起作用,哪里不起作用?
零、focus 希望在哪些情况下有用?10-02 定下的挑任务标准,后面的实验按它来看
focus:每一步动作之前,agent 用代码把这一步要关注的东西(要接近的物体、要避开的障碍、要走的路线)显式算出来、记下来,再据此决定动作。预期它在下面四种情况下有用:
| 情况 | 例子 | 本页对应的实验 |
|---|---|---|
| 1. 要记忆:部分可观测,东西不在画面里时仍要知道它在哪 | 转身后,身后的垃圾桶还在原处 | 捡垃圾:桶离开画面后撞上(3.1 节 B 类) |
| 2. 要建模当前操作物之外的世界状态 | 放罐子时桶被碰歪,要能察觉;柜子上还剩几个捕鼠器 | 捡垃圾的碰倒、新任务里的状态判断 |
| 3. 多个物体之间的空间关系要精确:间隙、相对布局、彼此的相对位置 | 底盘离桶只差几厘米;罐子对准桶口;汉堡装进袋子 | 探针(第一、二节);捡垃圾的放罐子(3.2 节);三个新任务 |
| 4. 单个物体的部件级几何:把手、边缘、孔、接触面 | 抓住把手、把东西插进孔里 | 本页的任务还没有专门测这一条 |
- 捡垃圾主要对应第 1、2 种;探针和三个新任务主要对应第 3 种;第 4 种还没有对应的任务。
一、Text-world model 和 Vision-world model 是否有 gap?同一个几何问题,分别用文字和图给 GPT-6,判断是否一样准
怎么测
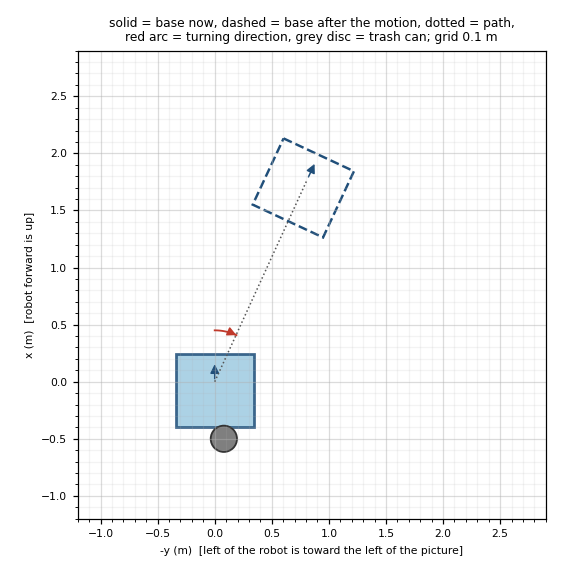
问题都是:机器人底盘按给定方式移动,途中会不会碰到地上的垃圾桶?标准答案由几何精确算出。同一道题用三种方式给出,只换表达方式,不许写代码。
① 坐标(文字)
② 简笔画(俯视示意图)
③ 真实相机画面
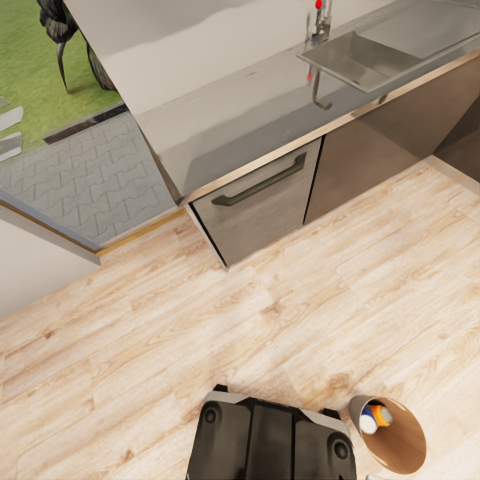
一共三组题。每道题都有两个版本:坐标版(文字)和图版,同一组题内部只换版本。
| 题组 | 题数 | 离"碰/不碰"的分界 | 图版 |
|---|---|---|---|
| 题组 1 | 40 | 3.5–83 cm(中位 13 cm) | 简笔画 |
| 题组 2(难题组) | 38 | 0.5–2.6 cm(在简笔画上只有 0.6–3 个像素) | 简笔画 |
| 题组 3 | 34 | 3–28 cm(其中 28 题超过 10 cm) | 真实相机画面 |
结果
看图版答错的题,读坐标版全部答对(难题组 13 题,配对检验 p ≈ 0.0002;题组 3 共 8 题)。
难题组的全部给法(5 种):用来看什么、结论
同一批 38 题,只换给 agent 什么、允许它怎么做,用来区分:结果差,是因为输入里没有精确数字,还是因为 agent 用看图的方式判断。
| 给法 | 结果 | 用来看什么 |
|---|---|---|
| 坐标,不许写代码 | 38/38 | 基准:几何信息以数字给出 |
| 坐标,允许写代码 | 37/38 | 有数字时,写代码还能不能再提高 |
| 坐标,让 agent 自己按坐标画简笔画,再看自己的图回答 | 36/38 | 图由 agent 自己画(尺寸、比例自定)时,看图判断准不准 |
| 简笔画,允许写代码 | 28/38 | 只有我们画的图时,写代码量像素能不能补回来(代码按颜色找出矩形和圆,量像素再换算成米) |
| 简笔画,不许写代码 | 25/38 | 只有我们画的图,只能看 |
结论:决定结果的是输入里有没有精确坐标,和 agent 看图还是写代码关系不大。
- 题组 1(离分界 3.5 cm 以上)看简笔画 39/40,和读坐标(40/40)差不多。
- 难题组的间隙在简笔画上只有 0.6–3 个像素,这个简笔画 ablation 还需要进一步 ablate。
二、让 coding agent 先用代码把 focus 建出来,能不能弥补这个 gap?先在最小的例子(探针)上看,再到真实任务里看
2.1 探针:只给相机画面,允许写代码
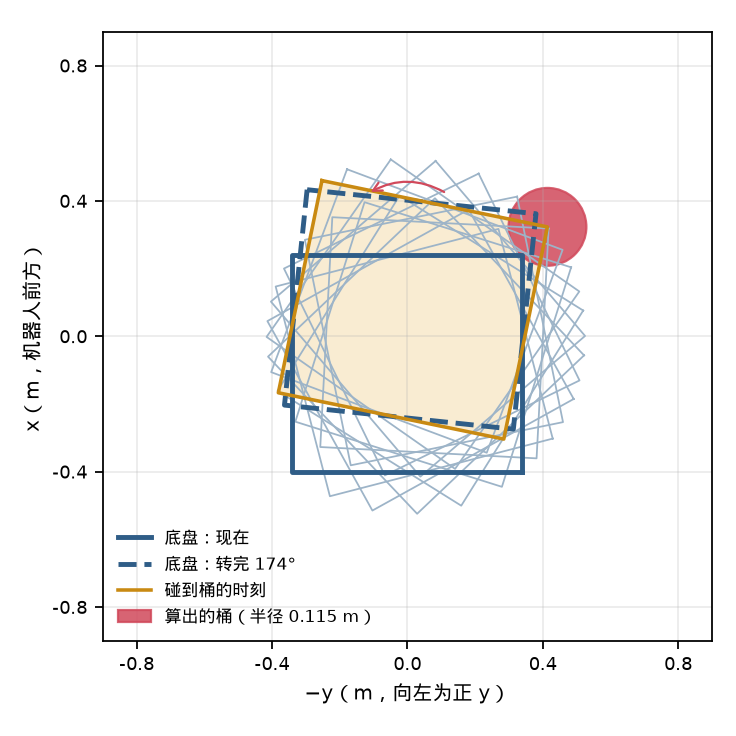
还是第一节题组 3 的相机画面题,题面另给精确的相机参数(焦距、相机在机器人上的位置和朝向)。下面是 agent 实际写的代码做的三步(第 1 题,原样复现):
1叠网格,读出桶口中心的像素
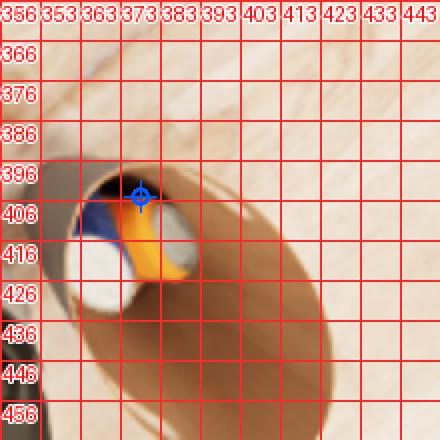
2从相机引射线,和桶口平面求交
3把移动切成 10 万小步,逐步算距离
2.2 真实任务:捡垃圾
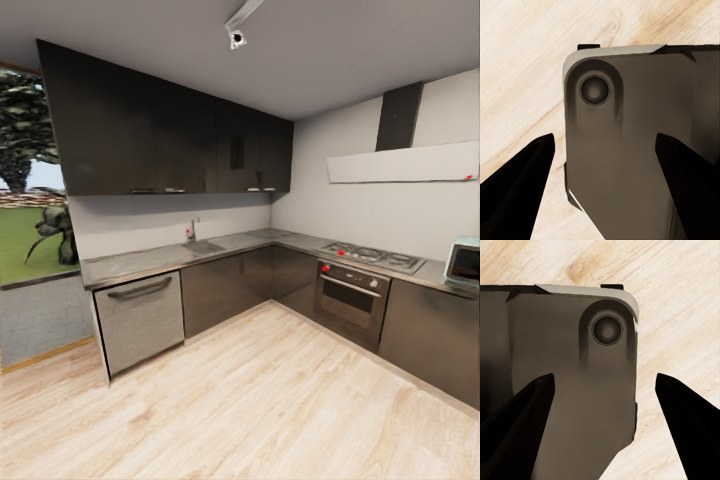
BEHAVIOR 的 picking_up_trash:把客厅的 3 个汽水罐放进厨房的垃圾桶。agent 只能通过观测(三路相机 + 头部深度)和底盘、手臂、夹爪的接口控制机器人;每调用一次观测算一轮,最多 120 轮;完成与否按仿真自带的目标判定(3 个罐子都在桶里)。
两组提示词只差一段:
- 不建 focus:只有目标、接口说明和共用规则。
- 分类 focus:每轮动作前把这一步依赖的东西记成 3D 表示,每一项标上四类角色之一:target要作用的物体,constraint要避开或不能扰动的东西,path要经过的路线,check动作后要核对的状态。
分类 focus 实际长什么样(一次运行里的一份记录)
focus_id: can_1_insert_into_tilted_bin
items:
  - id: soda_can_1_held
    role: target
    geometry.kind: held_can_grasp_point_base_m
  - id: kitchen_trash_can_candidate
    role: target
    geometry.kind: tilted_cylinder_estimate_odom_m
  - id: alignment_path
    role: path
    geometry.kind: eef_insert_path_base_m
  - id: rim_and_bin_body
    role: constraint
    geometry.kind: mouth_clearance_region
  - id: floor_and_counter
    role: constraint
    geometry.kind: obstacle_regions
  - id: alignment_check
    role: check
geometry.kind: proprio_and_image_check差 20 个百分点,Fisher 检验 p = 0.11。典型回放(6 次,附说明)→
其他 9 种 focus 写法(和不建 focus 的 13/40 相比)
只有"画成图"单独比较时 p = 0.045;一共比较了 10 种写法,按多重比较校正后都不显著。
schema: task_focus_v1
frame: robot_base_at_odometry_origin
updated_from_observation: turn 117
task_phase: cannot_continue_within_turn_limit
task_relevant_objects:
  soda_cans:
    - id: first_orange
      status: likely_inside_receptacle_after_release_at_corrected_mouth
      opening_center_odom_m: [1.05, -0.07, 0.21]
      evidence: released at corrected mouth after base approach; disappeared…
    - id: blue
      status: released_on_floor_outside_receptacle_after_missed_placement
      last_gripper_target_base_m: [0.62, -0.09, 0.25]
      source: turn 117 left-wrist RGB shows the blue can at the upper-left…
      post_release_floor_estimate_current_base_m: [0.65, 0.23, 0.06]
      post_release_uncertainty_m: [0.10, 0.10, 0.04]
    - id: third_orange
      status: on_living_room_floor_after_three_missed_grasps
      center_estimate_base_m: [0.50, -0.07, 0.06]
      source: turn 113 head and wrist RGB; repeated closes left it on the …
      uncertainty_m: [0.03, 0.03, 0.02]
      last_center_estimate_base_m: [0.50, -0.07, 0.06]
      robot_odometry_at_estimate_m: [-4.07, 3.21, -0.08]
      approx_center_odom_m: [-4.57, 3.23, 0.06]
  kitchen_trash_can:
    status: white_floor_receptacle_candidate_by_sink
…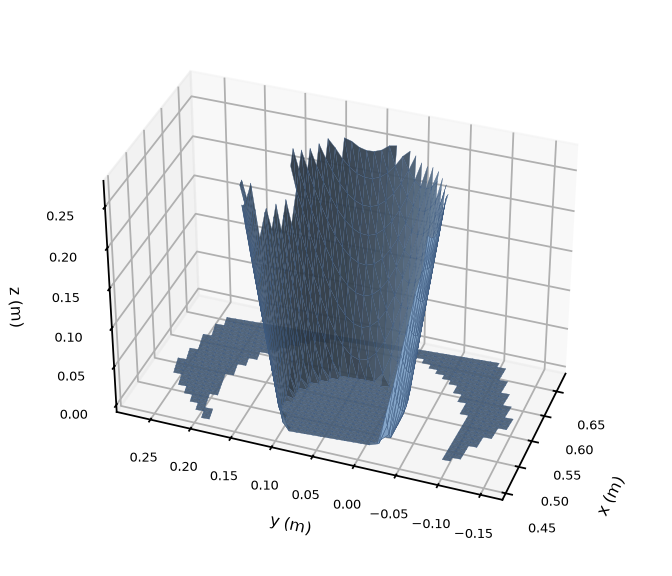
# t0013_trash_can_rim_interior.ply

Current head-depth mesh of the kitchen trash can rim and visible interior; the rim is raised from the floor, with the opening centered near base [0.56,0.05] m.

Frame: robot base frame, transformed from current head depth and the reported head-camera mounting pose; odometry at this observation is included as the robot base frame origin. Pixel polygon: [(207, 416), (272, 416), (281, 445), (273, 472), (210, 472), (198, 445)].
Mesh: 1029 vertices, 1722 triangles; organized samples every 2 pixels. It covers only the visible selected surface and is not a complete room model.
items:
  - role: target
    name: blue soda can near sliding-door threshold
    center_m: [-4.87, 3.05, 0.06]
  - role: target
    name: orange soda can beside the blue can
    center_m: [-4.66, 3.45, 0.08]
  - role: constraint
    name: sliding-door frame and threshold
    center_m: None
  - role: constraint
    name: living-room table/sofa and deposited can/bin back at the kitchen
    center_m: None
  - role: path
    name: continue along the clear living-room right-side corridor to a staging …
    center_m: None
  - role: check
    name: blue/orange can range and empty right gripper at staging point
center_m: Noneturn: 20
robot:
odom_pose: [-0.32, 0.72, 0.00]
body_extent_base_m:
x: [-0.40, 0.24]
y: [-0.34, 0.34]
z_max: 0.41
frame: odometry; robot faces +x in kitchen
relevant_scene:
trash_can_opening_center:
position_odom_m: [0.92, 0.27, 0.28]
outer_extent_m: [0.24, 0.24, 0.28]
opening_diameter_m: 0.16
position_sigma_m: [0.05, 0.05, 0.03]
state: open top; rim plane fitted from head depth rays, center pixe…
trash_can_interior_bottom:
position_odom_m: [1.00, 0.22, 0.17]
extent_m: [0.12, 0.12, 0.05]
state: visible through opening; confirms open interior
can_1_orange_held:
position_base_m: [0.16, -0.27, 0.54]
extent_m: [0.07, 0.07, 0.13]
state: held in right gripper, opening 0.0789 m
base_drop_approach:
position_odom_m: [0.40, 0.46, 0.00]
extent_m: [0.30, 0.30]
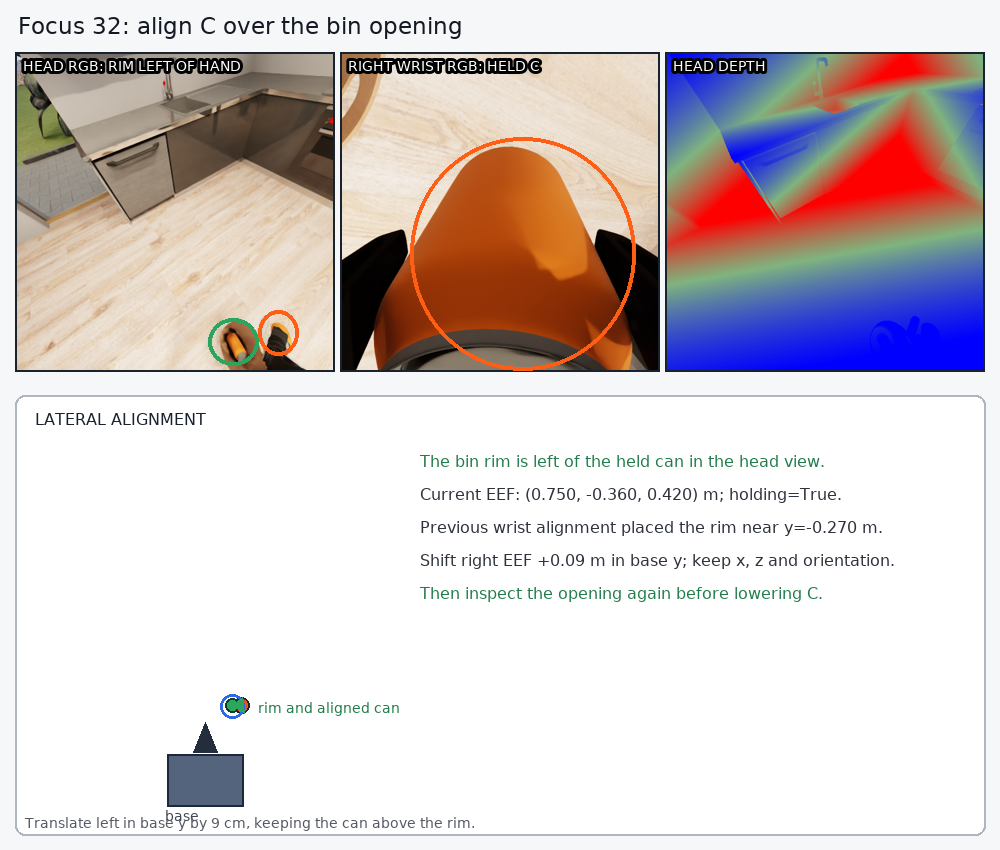
…
action: clockwise in-place base scan
frame: robot base / odometry
start_pose_odom:
  xy: [0.00, -0.00]
  yaw_rad: -0.32
target_pose_odom: [0, 0, -0.62]
swept_region_3d:
  base_body:
    shape: circular sector
    center_xy_m: [0, 0]
    radius_m: 0.53
    yaw_interval_rad: [-0.62, -0.32]
    z_interval_m: [0, 0.41]
  default_arms:
    shape: circular sector
    radius_m: 0.50
    yaw_interval_rad: [-0.62, -0.32]
    z_interval_m: [0.50, 0.65]
    holding: False
  boundary_samples_m:
    - - 0.43
      - -0.31
      - 0
    - - 0.43
      - -0.31
      - 0.41
…# Turn 20 — approach the kitchen trash can ## Focus before action (3D, episode odometry frame) - Robot pose `(-0.7167,0.3790) m`, yaw `≈−0.517 rad`. Right gripper holds can 1 at base-frame `(0.4524,-0.2231,0.5560) m`, opening `0.0729 m`; left arm empty. - Trash can: head-depth samples around its rim map to episode coordinates near center `(0.54,0.02,0.27) m`; rim points `(0.566,0.118,0.269)` and `(0.518,-0.073,0.268)` indicate an opening about `0.20 m` across. The can stands on the kitchen floor at `z≈0`, open and upright. Interior samples show its bottom near floor level. - Horizontal distance from base to bin center is about `1.31 m`. The visible kitchen floor between robot and bin is clear. Stop the base around `0.55 m` from the opening center to leave footprint clearance while allowing the arm to reach over the bin. ## Prediction before action Action: move base to `(0.02,0.17,-0.276)` in odometry, approaching along the measured line and facing the bin. Expected: base stops about `0.55 m` from the bin center; the bin remains upright and stationary; can 1 stays held at the same g…
# Persistent scene record

Coordinates are approximate, in the robot's odometry frame; at the initial pose the robot base is at (0, 0, 0) and faces +x. Current robot pose is approximately (0.032, 0.186, yaw −0.37 rad). Positions for objects not yet visible remain explicitly unknown until inspected.

| Object | Approx. position | Approx. size | State / evidence |
|---|---|---|---|
| Kitchen counter and cabinets | Ahead, about x=1.8–2.6 m; spans left/right of view | Countertop about 0.9 m high; cabinets full kitchen run | Fixed fixtures. Upper doors appear closed. |
| Sink and faucet | Ahead-left, around x=2 m, y=+0.5 m | Sink about 0.6 × 0.5 m; faucet about 0.3 m high | Fixed, empty as visible. |
| Dishwasher | Ahead-left, around x=1.6 m, y=+0.8 m | About 0.6 × 0.6 × 0.85 m | Door closed. |
| Stove and oven | Ahead-right, around x=1.9 m, y=−0.8 m | About 0.6 × 0.6 × 0.9 m | Fixed; oven do…
对照:CaP-X 的视觉差分(别人的方法)
CaP-X(arXiv 2603.22435)的做法:每次 agent 取观测时,另一个视觉语言模型(这里用 Gemini 3.1 Pro)比较这一次和上一次的头部相机画面,用文字告诉 agent 画面里变了什么、任务看起来是否完成。我们照它的提示词原文接入,其余与不建 focus 组相同。
结果:完成 2/8,碰倒垃圾桶 5/8。
- 探针:agent 先用代码把桶的位置算出来,看相机画面从 26/34 升到 34/34,和读坐标一样准。
- 难题组上看简笔画并写代码只到 28/38(需要进一步 ablate,见第一节备注)。
- 捡垃圾:分类 focus 完成 21/40(53%),不建 focus 13/40(33%),p = 0.11。
三、focus 在哪里起作用,哪里不起作用?拆开捡垃圾的失败原因,再看三个新任务
3.1 捡垃圾失败的主要原因:碰倒垃圾桶
不建 focus 的 40 次里 23 次碰倒了桶,分类 focus 18 次。按碰倒时头部相机画面里有没有桶分成三类:
A. 碰倒时桶在画面里
B. 画面里出现过桶,碰倒时不在
C. 碰倒前画面里从没出现过桶
3.2 起作用的地方:桶在画面里
A 类从 12 次降到 5 次(p = 0.10)。不建 focus 的 12 次里,10 次是手臂或夹爪的动作碰倒了桶,其中 8 次手里正拿着罐子。这正是探针里的情况:桶看得见,要精确判断手、罐子和桶口的相对位置。
3.3 不起作用的地方:头部相机从没拍到过桶
桶开局就在机器人正前方 0.49 m,但头部相机画面的下沿,在桶口高度处要到前方 0.75 m 才拍得到,所以开局画面里没有桶(2.2 节的开局观测)。agent 一开始移动底盘,就可能撞上它。
C 类分类 focus 没有减少(不建 5 次,分类 9 次)。
验证:直接在提示词里告诉 agent 桶的位置和尺寸,完成 7/8,碰倒 0/8(不建 focus 时完成 13/40,碰倒 23/40)。知道桶在哪,这个任务基本就能做成。
3.4 三个新任务(BEHAVIOR 2026 挑战赛)
每个任务三组:不建 focus、自由 3D focus、视觉差分,各 8 次,共 72 次。
放捕鼠器
放鞋
装外卖
| 任务 | 仿真判定完成 | 按人的标准完成 | 人的标准 |
|---|---|---|---|
| 放捕鼠器 | 0/24 | 不建 focus 3/8,3D focus 0/8,视觉差分 0/8 | 4 个都在地上,恰好 2 个离洗手池水平投影 0.30 m 以内 |
| 放鞋 | 0/24 | 0/24(最多放上 3 只) | 4 只都在衣帽架上 |
| 装外卖 | 0/24 | 0/24(没有汉堡进袋) | 3 个汉堡各在一个立着的袋子里,袋子都在箱子上 |
失败主要是下面几类:
夹不起物体
机器人翻倒
把一只鞋当成一双
仿真只认"正下方"
- 看得见:桶在画面里还被碰倒,从 12/40 降到 5/40(p = 0.10),多数是手拿罐子往桶口放的时候。
- 没进过画面:碰倒前头部相机从没拍到过桶,不建 focus 5/40,分类 focus 9/40;直接告诉 agent 桶的位置,完成 7/8、碰倒 0/8。
- 三个新任务失败在抓取、翻倒和理解目标上,测不出 focus 的作用。
Next step
- 任务:换成"桶看得见、需要精确判断位置"的场景(第〇节第 3 条),这正是探针里 gap 存在、捡垃圾里 focus 起作用的情况(3.2 节)。三个新任务要先去掉与 focus 无关的障碍(抓取、翻倒、判定规则),或者换任务。
- 第〇节第 4 条(部件级几何):补上对应的任务,候选是 CaP-X 的 Robosuite 精度任务和启能那边的拼装任务。
- 模型:以上结论都在 Luna 上得到;结论确定后在 Astra 上复验。