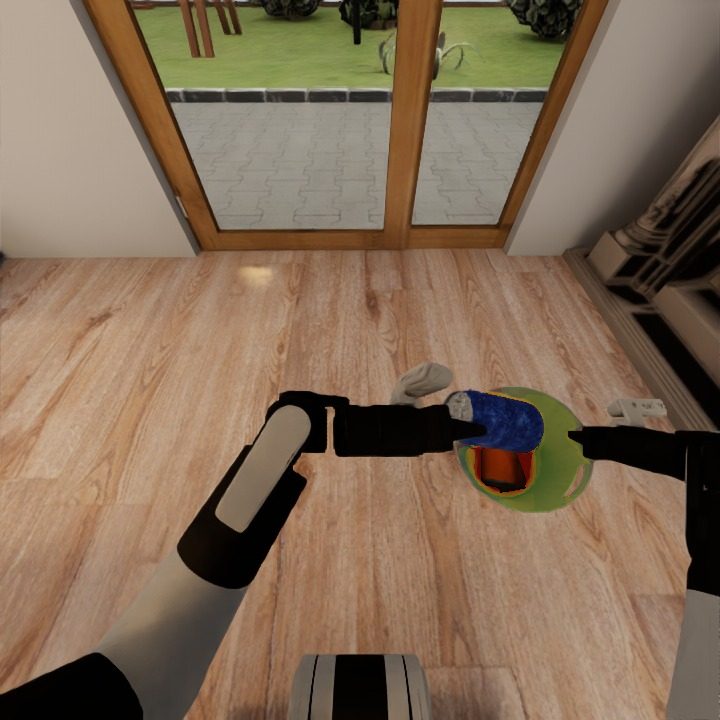
00_place_in_ashcan · place the can of soda in the trash can
skill = place in · target = trash can · demo episode_00010050 frame 6945 · GT mask 7538px(GT mask 来源: 开合/按钮=sim link, place-in=整物体)
输入
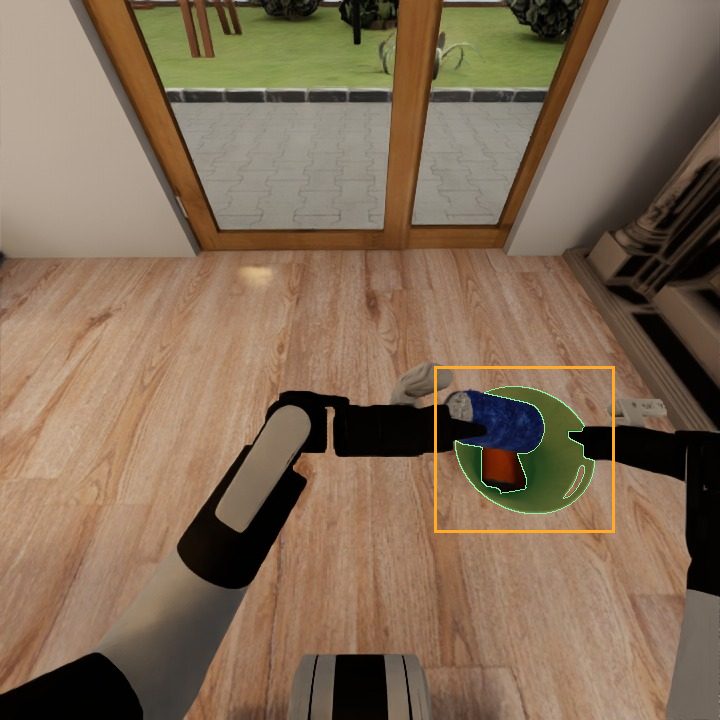
Arm1 · UAD — 原句→UAD 热图
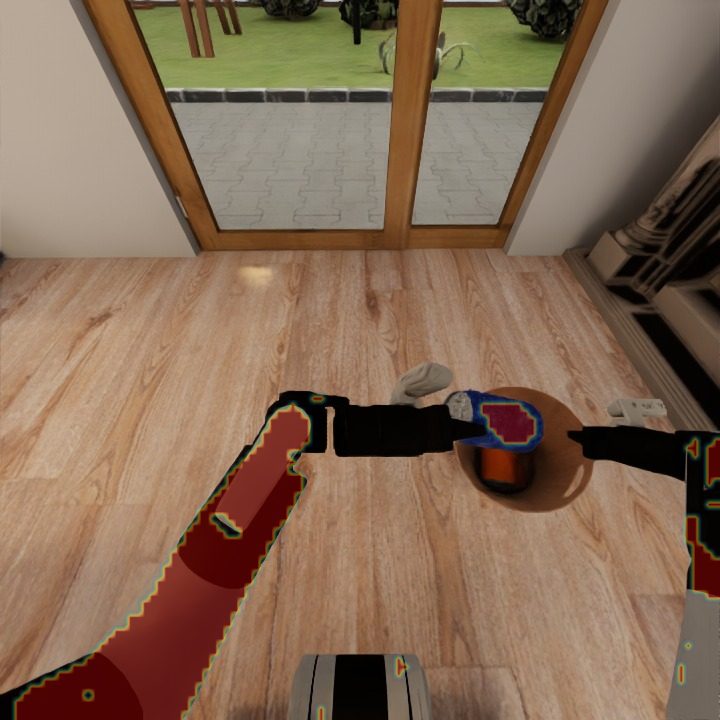
Arm2 · OpenSeg 原句 — 原句→OpenSeg (raw, 不取交集)
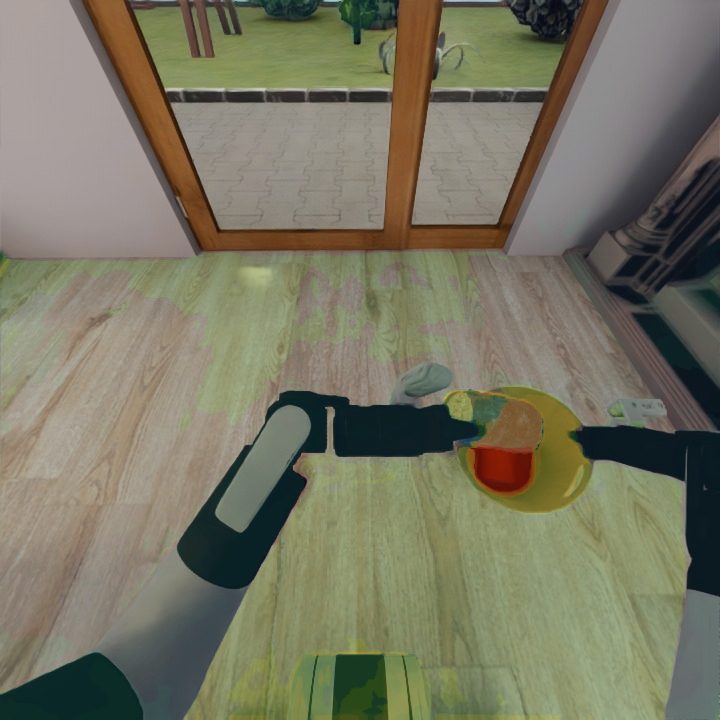
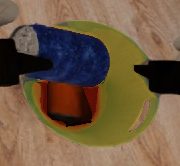
Arm3 · GPT短语+OpenSeg — GPT part 短语→OpenSeg→×GT mask
Step 1 · GPT 出 part 短语(输入=全图+crop)
GPT A-openseg — 完整 prompt
[system] You are helping build part-level annotations for robot manipulation data. Answer in JSON only.

[user] The robot's current subgoal is: "place the can of soda in the trash can". The target object is "trash can".
Image 1 is the full scene; image 2 is a close-up of the target object.
Name the subpart of the target object that should currently be visually focused for this subgoal.
Rules for the phrase (it will be fed to an open-vocabulary segmentation model that expects category-style queries):
- 1-4 words, nouns and adjectives ONLY, compound-noun style: "trash can opening", "door handle", "toggle button", "jar lid".
- No articles, no verbs, no clauses, no "that/which", no gerunds.
Output JSON (reason first): {"reason": "<one short sentence>", "part_phrase": "..."}
GPT: trash can opening — The soda should be placed into the open interior of the trash can.
Step 2 · OpenSeg(短语) → Step 3 · ×GT mask
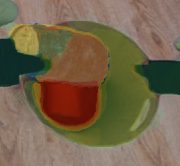
Arm4 · mask+DINO+GPT — mask 内 DINO 聚类→GPT 选簇
Step 1 · GT mask 内 DINO 特征 KMeans-6 聚类
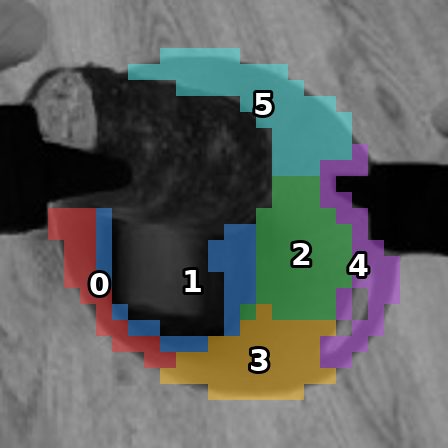
Step 2 · GPT 选簇(输入=全图+crop+聚类图)
GPT B-cluster — 完整 prompt
[system] You are helping build part-level annotations for robot manipulation data. Answer in JSON only.

[user] The robot's current subgoal is: "place the can of soda in the trash can". The target object is "trash can".
Image 1 is the full scene, image 2 is a close-up of the target object, image 3 shows the same close-up divided into numbered colored regions (clusters).
Which cluster is the subpart that should currently be the visual focus for this subgoal?
Rules:
- Pick 1-2 cluster numbers. Prefer the single best cluster; add a second only if the focused subpart clearly spans two.
- If no cluster matches, return an empty list.
Output JSON (reason first): {"reason": "<one short sentence>", "clusters": [..]}
GPT 选簇: [2] — The trash can opening and interior are primarily represented by cluster 2.
Step 3 · 选中簇 → mask
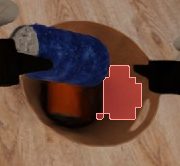
Arm5 · SAM3 原句 — 原句直接喂 SAM3 (crop)
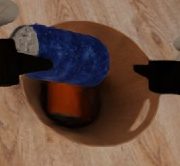
Arm6 · GPT短语+SAM3 — GPT part 短语→SAM3 (crop)
Step 1 · GPT 出 SAM3 风格短语(输入=全图+crop)
GPT A-sam3 — 完整 prompt
[system] You are helping build part-level annotations for robot manipulation data. Answer in JSON only.

[user] The robot's current subgoal is: "place the can of soda in the trash can". The target object is "trash can".
Image 1 is the full scene; image 2 is a close-up of the target object.
Give a short plain noun phrase naming the subpart of this object that should currently be visually focused for this subgoal, in the style of segmentation prompts like "door handle", "bottle cap", "lid of the jar".
Rules: 1-5 words; plain noun phrase only ("X" / "adjective X" / "X of the Y"); no "that/which" clauses, no gerunds, no past participles.
Output JSON (reason first): {"reason": "<one short sentence>", "part_phrase": "..."}
GPT: opening of the trash can — The soda should be placed into the trash can opening.
Step 2 · SAM3(crop, 短语)
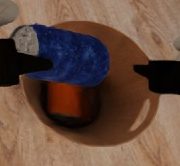
Arm7 · GPT点+SAM1 — GPT 网格点→SAM1 point prompt
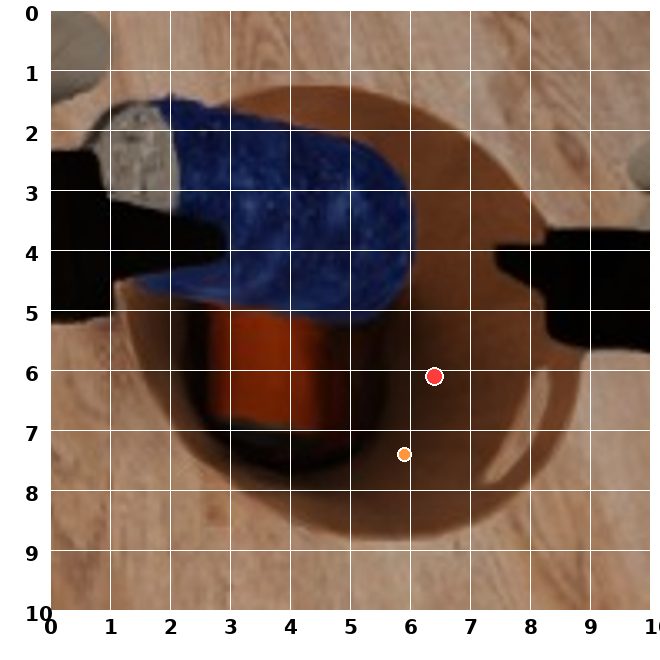
Step 1 · GPT 在坐标网格上给点(输入=全图+网格 crop)
GPT C-points — 完整 prompt
[system] You are helping build part-level annotations for robot manipulation data. Answer in JSON only.

[user] The robot's current subgoal is: "place the can of soda in the trash can". The target object is "trash can".
Image 1 is the full scene. Image 2 is a close-up of the target object with a coordinate grid: x runs 0 (left) to 10 (right), y runs 0 (top) to 10 (bottom). Grid lines are only visual aids - coordinates are continuous, decimals encouraged (e.g. x=3.7).
Give 1-3 points that lie ON the subpart of this object that should currently be the visual focus for this subgoal.
Rules:
- Points must be inside the subpart, not on its boundary or on other parts.
- First point = the most central/confident location.
Output JSON (reason first): {"reason": "<one short sentence>", "points": [[x, y], ...]}
GPT 点: [[6.4, 6.1], [5.9, 7.4]](红=第一/最自信点) — The visual focus is the open interior of the trash can where the soda can should be placed.
Step 2 · SAM1 point-prompt,多点取并集